76% Stuck Their Agents in Pilot. The Tax Is Human Hours
We have already written the guardrails version and the failure-mode version. This week a vendor paid for a poll and the numbers are ugly enough to use.
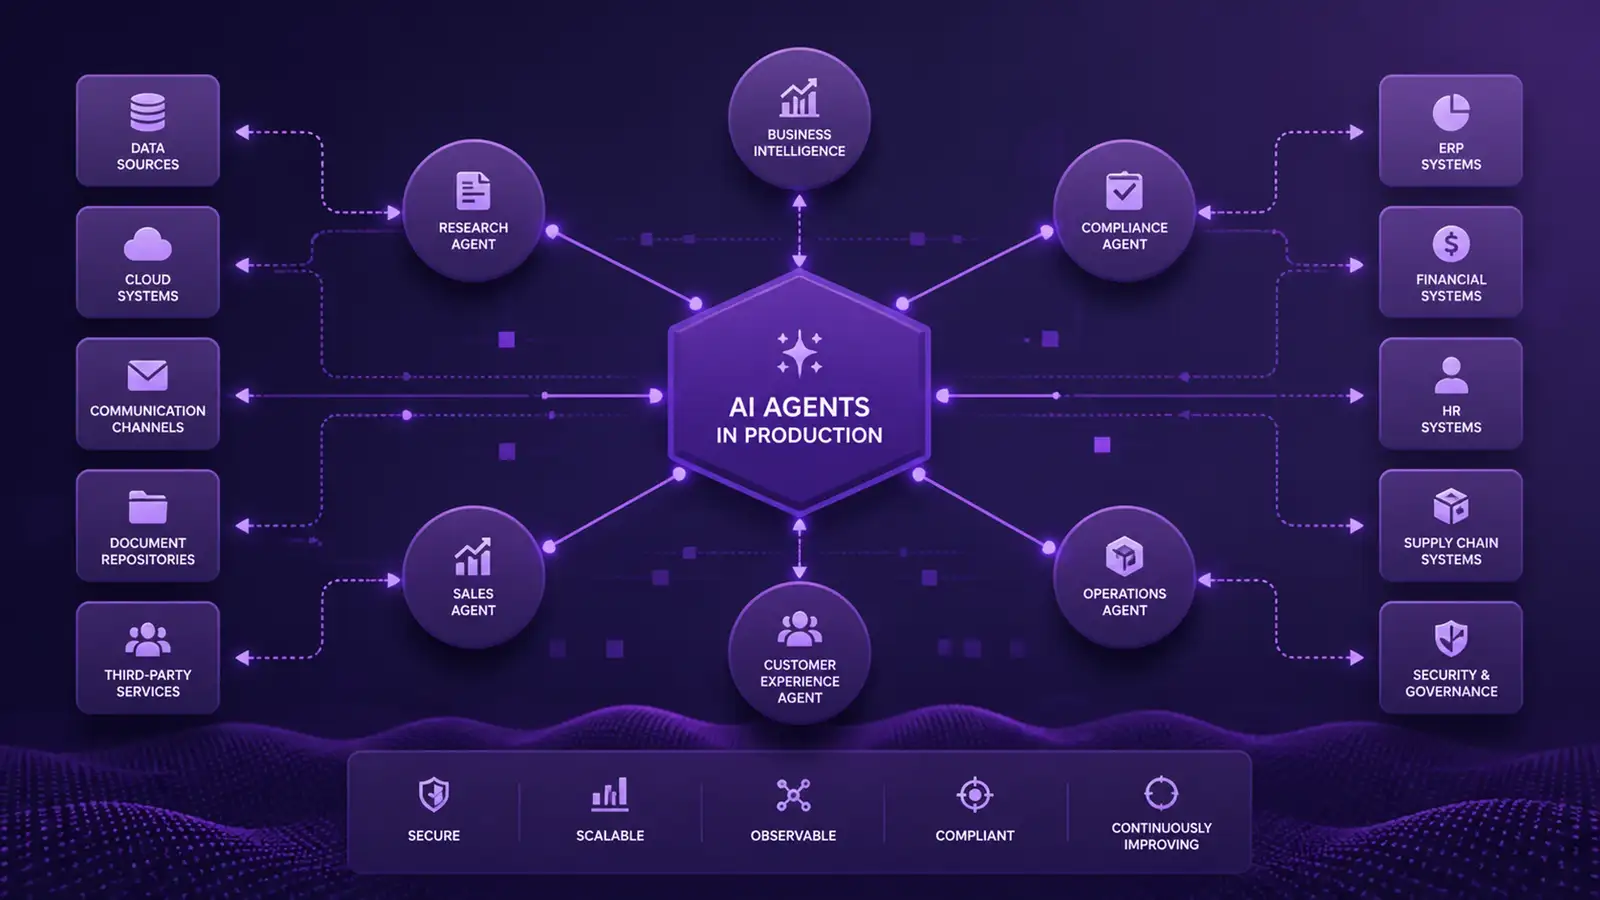
Collibra put out The 2026 Hallucination Tax Report on September 18. The Harris Poll ran it online in the United States from August 5 to 11, among 306 adults aged 21 and up who work full time as data, privacy, or AI decision-makers. That is a small, sponsored sample. It is not a census of the Fortune 500. It is also not a blogger’s vibes. Nine in ten of those respondents said their organizations are actively deploying autonomous AI agents. More than three-quarters, 76 percent, said they hit critical roadblocks trying to move from pilot to full production in the past 12 months.
Read that pair twice. Almost everyone is running agents. Most of them cannot get the agents out of the sandbox without the project stalling. The governance gap we flagged in August is not a thought experiment in this sample. It is the majority outcome.
What they are calling a tax
Felix Van de Maele, Collibra’s co-founder and CEO, used the phrase “hallucination tax” for the hidden cost of manual oversight, rework, and risk that grows with every new agent in production. His line, via the HPC Wire write-up: if human workers spend countless hours validating every response, the business value of automation disappears and the company still carries the burden.
That is a sales sentence. The mechanism underneath it is ordinary. An agent that drafts a customer email, a policy answer, or a ticket resolution still has to be right. If the retrieval index is stale, someone with a salary re-reads the output. If that someone is in the loop on every run, you did not automate. You added a junior that types fast and a senior that proofreads.
Eighty-seven percent of the decision-makers said their teams regularly re-verify that the context their agents have remained accurate and current. That is the tax in a percentage. It is not “the model hallucinated a court case.” It is “we cannot trust the files we gave it last month.” Collibra’s own diagnosis is missing structured context and runtime governance, which is exactly what Collibra would like to sell. Discount the vendor. Keep the 87 percent. If your agents team has a standing meeting called “context review,” you are in that bucket.
I am not going to complete the 72 percent and 51 percent findings. The extract cut those sentences in half. Incomplete polls do not get invented clauses on this site.
Pilots are cheap. Production is a second product
A pilot can live on a slide. Production needs identity, logging, rollback, and a person who gets paged. The survey’s 12-month window matters. These are not shops that “haven’t tried yet.” They tried, and the promotion from demo to default path failed often enough that three-quarters of the room said so.
The failure is usually not the model card. GPT-class models write fluent paragraphs. Agents fail when they take actions: open a pull request, change a customer record, call an MCP server nobody inventoried. That is a different risk register from chat. You can hide a wrong paragraph. You cannot hide a wrong refund.
If 90 percent are deploying and 76 percent are blocked on the promotion, the honest org chart is: a lab that ships demos, and a production org that will not take the page. The C-suite conversation Van de Maele described, from theory to “measurable business impact,” dies in that handoff. Impact is not tokens generated. Impact is a workflow that runs without a human re-checking the context every morning.
Snyk’s week, in scan volume
Snyk’s own note on September 17 is also a vendor document. The volumes are the part I will keep. Snyk says it now processes 2.4 million agent supply-chain scans a month and 4.2 million agent behavior checks a day across more than 417,000 onboarded machines, including Fortune 50 deployments. Across 4,800-plus customers, newly introduced issues rose 108 percent from Q4 2024 to Q1 2026, before agentic code generation reached full scale. Evo, the agent-security product, is claimed to go live in a single quarter: 76 percent of customers who bought it in Q2 were in production before the quarter closed. That 76 percent is a coincidence with Collibra’s 76 percent, not a confirmation. One is “stuck.” One is “we installed the scanner.” Do not mash them into one chart.
The technical claim I believe without buying the rest: coding agents pull unvetted MCP servers and third-party skills and then execute production actions that used to need a human. Traditional tooling scans artifacts. It does not scan the toolchain an agent assembled at runtime. Find it, log it, wait for a developer is a queue that grows while the agent keeps writing.
If your security team still tickets CVE-looking findings from a nightly image scan, an agent that installed a skill at 2 a.m. is off to the side of that process. That is the Collibra tax in another costume. Someone has to look.
The rest of the aisle is selling kill switches
SiliconANGLE’s September 18 roundup reads like a trade-show bag. Exaforce added a kill switch for agents that go rogue. Cohesity’s Agent Resilience is a rollback for agents that go wrong. Arcjet launched runtime security to track agents in production. StackHawk’s Wingman is supposed to fix security flaws while the agent is still coding. Akuity and StackGen are selling governed paths into production. Splunk is rebuilding around agents. HubSpot is rebuilding CRM around contextual AI.
I am not ranking those products. I am noting that the market is no longer selling “chat with your PDF.” It is selling the brake pedal. That only happens when enough buyers have met the 76 percent wall. Kill switches are not a vision of autonomous work. They are an admission that the loop cannot be trusted unsupervised.
If you are writing a board memo this month, the useful sentence is not “we have agents.” It is “what percent of agent runs are still re-verified by a person, and what is that person’s other job.” Collibra’s 87 percent is the number I would put in the memo, with the sample size next to it, 306, Harris Poll, August 5–11, paid for by a data-governance vendor.
What to do that is not a purchase order
Inventory the agents that can write, not just the ones that talk. Anything with a tool, a browser, a ticket API, or an MCP handle is in the production conversation even if the slide says pilot.
Put a freshness date on every corpus the agent is allowed to read. 87 percent of this sample already re-check. Make the check a timestamp, not a feeling.
Log actions, not prompts. Prompts are literature. Actions are the incident.
Decide who can halt a run. If the answer is “the intern who demoed it,” you are the SiliconANGLE customer for a kill switch you have not bought yet.
Do not wait for a smarter model to erase the tax. Van de Maele said organizations cannot simply deploy smarter models; they have to put context and control in the workflow. That sentence is self-serving and still right. A better model with last quarter’s policy deck will still need a human. The tax is on the files.
What the hours look like on a real team
I keep hearing the same three jobs sharing one calendar: the person who demoed the agent, the person who owns the corpus, and the person who gets the angry Slack when the agent closes the wrong ticket. In the Collibra sample those jobs collapse into “decision-maker.” In a company they are three salaries. The 87 percent who re-verify context are often the corpus owner, doing a job that was never in the original headcount request.
Write the runbook as if the demo person is on PTO. If the agent cannot run, that is a product with a bus factor of one, which is a pilot. If it can run and someone still re-reads every output, that is the tax. The second case is the one the survey is about. The first case is worse and does not even make the 76 percent, because you never tried production.
MCP servers belong on that runbook. Snyk’s complaint is that agents assemble a toolchain at runtime. Your allowlist has to be a list of servers, not a feeling about “internal tools.” If a skill can fetch, it can fetch a prompt. If it can write, it can write a secret into a ticket. Log both.
The +108 percent jump in newly introduced issues, Q4 2024 to Q1 2026, is Snyk talking about code, not chat. Agent-written code widens a backlog that was already growing. Security teams that measure “mean time to remediate” without measuring “mean time to generate” will watch the first number get worse and blame the scanner. Blame the merge volume.
Exein raising $270 million at $1.7 billion, Mind raising $72 million, Comp AI raising $34 million, all in the SiliconANGLE bag, tells you the same story with a cap table. Money is going to companies that promise to stop agents, contain agents, or paper over agents. That is not a boom in autonomy. That is a boom in supervision software.
How not to brief this
Do not tell the board “76 percent of companies fail at agents.” Tell them “a Harris Poll of 306 US data and AI managers, paid for by Collibra, in August, found 76 percent hit a wall between pilot and production, and 87 percent still re-check context.” Then show your own babysitter hours. If you cannot show the hours, you are in the 76 percent and you do not know it.
Do not mash Snyk’s 76 percent of Evo buyers going live in-quarter with Collibra’s 76 percent stuck. One is a scanner install. One is a promotion failure. Same digit, opposite verb.
The survey does not tell you your company is doomed. It tells you that “we deployed agents” is the common state and “they run without a babysitter” is not. The gap is the story. Measure the babysitter hours. That is the only number that decides whether the pilot was a product or a cost.
Collibra wants you to download the full report from collibra.com. Do that if you need the truncated 72 percent and 51 percent lines I refused to guess. The HPC Wire recap is enough to brief. The PDF is for the person who has to defend the sample. 306 people, August 5 to 11, US only, data and AI managers. That is the box. Stay in it.
Related Articles
Microsoft's Copilot Super App Meters the Agents
Enterprise AI Agents Are Reaching Production — But Governance and Security Aren't Ready